Telemetry data warehousing and analytics

A managed data platform for telemetry analytics

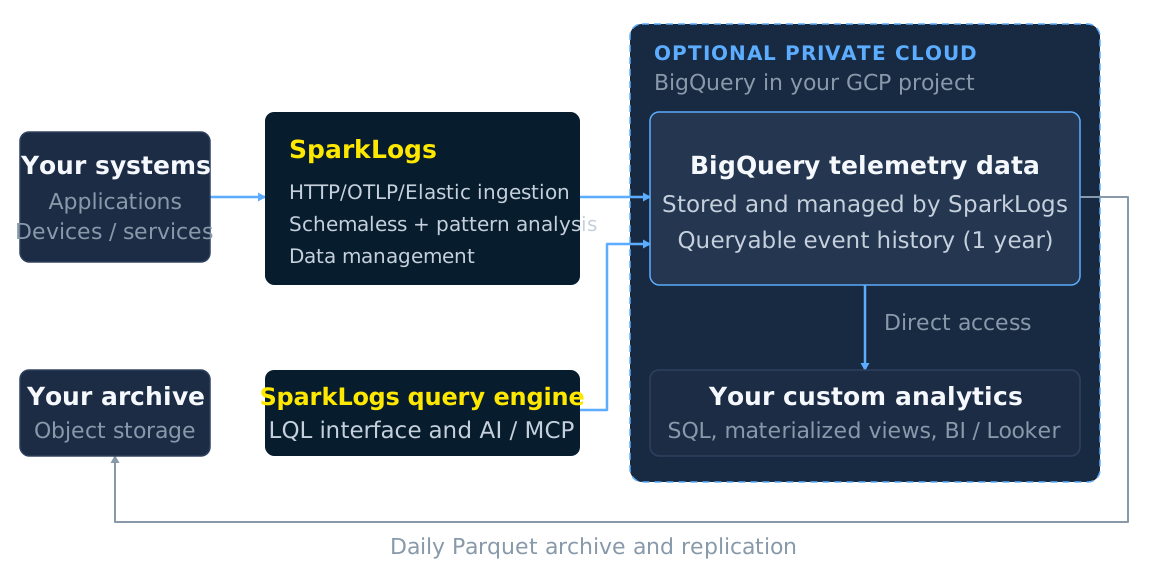
SparkLogs combines petabyte-scale telemetry ingestion, flexible querying, and purpose-built MCP tools for AI-driven data exploration and analysis. Built on BigQuery, it manages evolving event data, queryable history, and portable archives, with optional Private Cloud access for custom analytics in your own Google Cloud Platform (GCP) project.

From event ingestion to custom analytics

Use SparkLogs as the managed foundation for telemetry data, then extend it with the analytical workflows your organization needs.

SparkLogs telemetry platform with optional Private Cloud, BigQuery, custom analytics, and archive replication

Ingest evolving event data

SparkLogs automatically scales ingestion to accommodate sharp changes in event volume, including sudden bursts from idle. Send nested JSON and custom fields through open protocols without defining an ingestion schema in advance. SparkLogs handles field extraction and mapping in realtime. The fully managed service requires no customer-managed ingestion servers or clusters.

Explore data with purpose-built AI tools

SparkLogs MCP tools help AI agents discover data, construct queries, and run aggregate and conditional analysis. Teams can also use LQL, the SQL-like query language, and full-text search in the SparkLogs interface. LQL is specialized for semi-structured data, with powerful operators, multivariate typing, and array expressions.

Custom data workflows and dashboards

With the Private Cloud option, you store your telemetry in BigQuery in your own GCP project. Your team can build SQL models, materialized views, and reporting workflows directly on that data, using BigQuery and compatible BI tools. SparkLogs provides ingestion, data management, query tools, and archive replication. Your team develops the business-specific analytics.

Private Cloud is optional. SparkLogs Cloud provides the managed SparkLogs platform, with hosted data storage and query processing.
Queryable history and a portable archive

SparkLogs Cloud plans retain data for live querying for up to 1 year. Private Cloud plans can be configured for longer retention and live querying periods.

Daily archives store ingested data in compressed, Hive-partitioned Parquet. Replicate them to your own AWS S3, Google Cloud Storage, Azure Blob Storage, or S3-compatible bucket for separately managed retention and downstream analysis.

Learn about archiving and replication

Hierarchical organization and access control

Organize data into hierarchical scopes and control access by role. Configure users for aggregate-only queries or permit access to individual event data, including through MCP.

SparkLogs permissions govern access through SparkLogs. Direct BigQuery access follows your GCP permissions. Data is encrypted in transit and at rest.

Visit the Security and Trust Center

Standards-based ingestion

Capability
Detail
Native APIHTTPS JSON ingestion for structured and semi-structured events.
OpenTelemetryOTLP/HTTP logs ingestion with JSON and Protobuf encodings.
Other ingestion APIsElasticsearch bulk ingestion and Loki push API support.
Open-source shippersVector, Fluent Bit, OpenTelemetry Collector, and Grafana Alloy.
Event structureNested JSON and custom fields without a predefined ingestion schema. Automatic standard-field mapping, storage, and querying of any arbitrarily complex JSON.

Query through SparkLogs, from your own AI systems, or directly in BigQuery

LQL query language

SQL-like, type-aware queries over event fields, with full-text search and interactive exploration.

LQL syntax

AI through MCP

Purpose-built tools for data discovery, aggregate and conditional queries, and event exploration within each user's permissions.

Connect your AI

Adaptive-scale querying

Enables interactive exploration of 100+ billion event datasets, dynamically zooming in on areas of interest.

How adaptive querying works

Private Cloud

Direct BigQuery access for customer-built SQL, materialized views, BI, and analytical workflows.

Private Cloud setup

Query billions of events in seconds

SparkLogs supports analysis across tens of billions of events, with demonstrated at-scale query times under 10 seconds without sampling.

For queries in your private-cloud project, BigQuery fluid scaling adjusts query capacity each second and compute bills by the second. Capacity scales up from and back to zero within seconds. Query times depend on workload and configuration.

Customer Case Study: Big Time Studios

Big Time Studios uses SparkLogs to ingest and analyze game telemetry to optimize player experience and game economy. The studio combined logging and analytics in one platform, retiring 3 fragmented data silos and reducing costs by 80%.

Read the customer story

Choose where your data lives

SparkLogs Cloud
SparkLogs Private Cloud
Data storageSparkLogs-managedBigQuery in your GCP project
SparkLogs interface and MCPAvailableAvailable
Direct BigQuery accessNot providedAvailable
Parquet archive replicationSupportedSupported

Discuss your telemetry and reporting requirements

Review your data sources, event volume, retention needs, and reporting queries with the SparkLogs team.

We can help you assess fit for:

  • Ingestion volume, burst patterns, and protocol choices
  • SparkLogs Cloud vs Private Cloud deployment
  • Retention, archiving, and BigQuery analytics workflows
  • MCP and LQL access for your team and AI systems

Speak with an expert

30-day enterprise trial available. Speak with us if you need custom volume pricing.